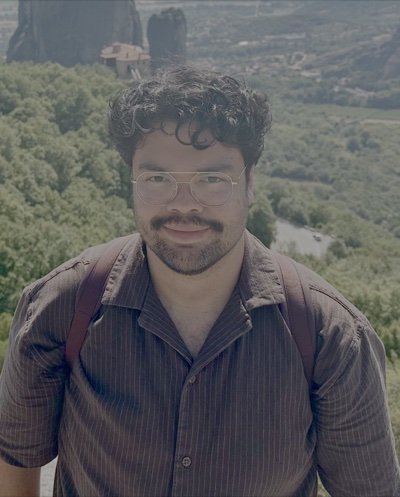
I am a Ph.D. candidate at the University of Massachusetts Amherst co-advised by Przemyslaw A. Grabowicz and Yair Zick.
I am on the job market. I expect to complete my Ph.D. in early 2027 and am seeking postdoctoral positions, fellowships at AI safety labs, and industry research roles. My expertise is in explainability and interpretability, responsible AI, and the evaluation and auditing of machine learning systems, recently focusing on large language models. If you are hiring, feel free to reach out.
My dissertation focuses on methods at the intersection of explainability and fairness: learning methods that prevent discrimination in an explainable way, and explanation and recourse methods that are fair and robust. My recent work extends these methods to large language models and to the tools used to audit them, using red teaming, bias benchmarking, and mechanistic interpretability to evaluate and explain model behavior and to expose the failures that popular benchmarks can hide. Currently, I am studying how safety-trained LLMs behave on bias benchmarks, whether their self-explanations can be trusted, and whether LLM evaluators favor certain personas, in collaboration with Google DeepMind and MassMutual.
I am a GEM Ph.D. Fellow. At UMass Amherst I received the 2023 Commitment to Diversity Award and was a finalist for the 2022–23 Distinguished Teaching Award, the university’s highest recognition for teaching.
My CV can be found here.